inference

Frontier Models
Access all of the smartest models.
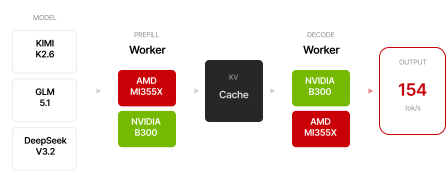
ai& runs the frontier open-weight models Kimi, DeepSeek, GLM outperforming proprietary models. For enterprise clients, ai& post-trains on top of these for domain-specific performance.
Heterogeneous Compute
Run on heterogeneous Nvidia and AMD hardware, efficient AI serving through at scale disaggregation and optimization to maximising utilisation and throughput, and passing the savings directly to you.

Model Pricing
Priced for production scale.
Industry-leading cost per token, with no contracts required. Run at any scale and pay only for what you use.
Model Name
Input Token Pricing / 1M
Output Token Pricing / 1M
"/><stop offset="1" stop-color="rgb(255, 255, 255)"/></linearGradient><linearGradient id="fy2kFJphA-855988464-linear-gradient" x1="1" x2="0" y1="0.7846116017641942" y2="0.2153883982358058"><stop offset="0" stop-color="rgba(105, 100, 237, 0.53)"/><stop offset="1" stop-color="rgb(255, 255, 255)"/></linearGradient><linearGradient id="kXoSpLec_-855988464-linear-gradient" x1="0.49749868365793026" x2="0.5025013163420697" y1="0" y2="1"><stop offset="0" stop-color="rgba(105, 100, 237, 0.53)"/><stop offset="1" stop-color="rgb(255, 255, 255)"/></linearGradient><linearGradient id="pzNl43GW6-855988464-linear-gradient" x1="1" x2="0" y1="0.20955834714214805" y2="0.790441652857852"><stop offset="0" stop-color="rgb(97, 92, 237)"/><stop offset="1" stop-color="rgb(99, 45, 228)"/></linearGradient><linearGradient id="SpY9X9apg-855988464-linear-gradient" x1="0" x2="1" y1="0.4975124378109453" y2="0.5024875621890547"><stop offset="0" stop-color="rgb(97, 92, 237)"/><stop offset="1" stop-color="rgba(97, 92, 237, 0)"/></linearGradient><linearGradient id="NaGTTODDA-855988464-linear-gradient" x1="0.7869394576985561" x2="0.2130605423014439" y1="5.551115123125783e-17" y2="1"><stop offset="0" stop-color="rgb(167, 165, 246)"/><stop offset="1" stop-color="rgba(97, 92, 237, 0)"/></linearGradient></defs><path d="M 15.355 30.708 C 15.148 30.708 14.953 30.595 14.849 30.412 L 14.807 30.337 L 12.907 27.015 L 4.805 27.015 C 4.703 27.015 4.602 26.989 4.513 26.936 C 4.423 26.883 4.349 26.808 4.299 26.72 L 2.189 23.03 C 2.136 22.939 2.11 22.838 2.11 22.734 C 2.11 22.63 2.136 22.529 2.189 22.439 L 4.13 19.044 L 0.079 11.957 C 0.028 11.867 0 11.765 0 11.662 C 0 11.558 0.026 11.456 0.079 11.366 L 2.189 7.676 C 2.239 7.588 2.313 7.513 2.403 7.46 C 2.49 7.407 2.593 7.38 2.695 7.38 L 6.579 7.38 L 10.629 0.296 C 10.681 0.205 10.755 0.132 10.843 0.079 C 10.93 0.026 11.033 0 11.135 0 L 15.355 0 C 15.563 0 15.757 0.112 15.862 0.296 L 17.804 3.692 L 25.907 3.692 C 26.01 3.692 26.11 3.719 26.2 3.772 C 26.29 3.825 26.364 3.897 26.414 3.988 L 28.524 7.678 C 28.577 7.768 28.603 7.87 28.603 7.974 C 28.603 8.077 28.577 8.179 28.524 8.269 L 26.582 11.664 L 30.632 18.751 C 30.684 18.839 30.711 18.943 30.711 19.046 C 30.711 19.15 30.684 19.251 30.632 19.342 L 28.522 23.034 C 28.472 23.122 28.397 23.197 28.308 23.25 C 28.22 23.301 28.118 23.33 28.015 23.33 L 24.134 23.33 L 20.082 30.417 C 20.032 30.505 19.957 30.58 19.868 30.633 C 19.778 30.683 19.678 30.712 19.575 30.712 L 15.355 30.712 Z" fill="rgb(255, 255, 255)" height="30.712120000000002px" id="BTyfhcAb0" transform="translate(0.141 1.143)" width="30.710575px"/><path d="M 4.01 0 L 6.12 3.69 L 4.01 7.38 L 20.892 7.38 L 18.782 11.07 L 2.322 11.07 L 0 7.012 Z" fill="url(%23kScUotMaP-855988464-linear-gradient)" height="11.07038px" id="kScUotMaP" transform="translate(7.266 1.732)" width="20.892380000000003px"/><path d="M 2.11 18.455 L 4.22 14.765 L 8.44 14.765 L 0 0 L 4.218 0 L 12.448 14.394 L 10.128 18.457 Z" fill="url(%23fy2kFJphA-855988464-linear-gradient)" height="18.45727px" id="fy2kFJphA" transform="translate(2.836 9.111)" width="12.448060000000002px"/><path d="M 16.882 7.012 L 12.66 7.012 L 10.552 3.322 L 2.11 18.084 L 0 14.397 L 8.23 0.002 L 12.874 0 Z" fill="url(%23kXoSpLec_-855988464-linear-gradient)" height="18.0845px" id="kXoSpLec_" transform="translate(13.391 13.174)" width="16.8821px"/><path d="M 30.905 18.817 L 27.318 12.544 L 26.897 11.805 L 28.795 8.485 C 28.86 8.371 28.893 8.243 28.893 8.117 C 28.893 7.991 28.86 7.861 28.795 7.749 L 26.685 4.058 C 26.619 3.944 26.528 3.853 26.419 3.789 C 26.309 3.725 26.183 3.69 26.054 3.69 L 18.035 3.69 L 16.135 0.368 C 16.004 0.141 15.764 0 15.502 0 L 11.282 0 C 11.151 0 11.026 0.035 10.917 0.099 C 10.808 0.163 10.714 0.256 10.648 0.368 L 7.062 6.644 L 6.64 7.38 L 2.842 7.38 C 2.711 7.38 2.586 7.416 2.477 7.48 C 2.368 7.543 2.274 7.636 2.208 7.749 L 0.098 11.434 C 0.033 11.549 0 11.677 0 11.803 C 0 11.928 0.033 12.059 0.098 12.171 L 4.109 19.183 L 2.208 22.505 C 2.143 22.619 2.11 22.747 2.11 22.873 C 2.11 22.999 2.143 23.129 2.208 23.241 L 4.318 26.931 C 4.384 27.046 4.478 27.137 4.585 27.201 C 4.694 27.265 4.821 27.3 4.95 27.3 L 12.968 27.3 L 14.868 30.622 C 14.999 30.849 15.239 30.99 15.502 30.99 L 19.722 30.99 C 19.853 30.99 19.977 30.955 20.086 30.891 C 20.196 30.827 20.29 30.734 20.353 30.622 L 24.363 23.61 L 28.162 23.61 C 28.293 23.61 28.417 23.575 28.526 23.511 C 28.636 23.447 28.729 23.354 28.793 23.241 L 30.903 19.551 C 30.968 19.437 31.001 19.309 31.001 19.183 C 31.001 19.057 30.968 18.927 30.903 18.815 Z M 11.282 0.732 L 13.392 4.425 L 11.282 8.115 L 28.164 8.115 L 26.054 11.805 L 9.593 11.805 L 7.271 7.744 Z M 12.97 26.57 L 4.952 26.57 L 7.062 22.875 L 11.282 22.875 L 2.842 8.113 L 7.062 8.113 L 9.172 11.803 L 15.29 22.507 L 12.97 26.568 Z M 26.051 19.185 L 23.942 15.495 L 15.502 30.258 L 13.392 26.568 L 15.504 22.877 L 21.624 12.175 L 26.268 12.175 L 30.276 19.185 L 26.054 19.185 Z" fill="url(%23pzNl43GW6-855988464-linear-gradient)" height="30.99px" id="pzNl43GW6" transform="translate(0 1)" width="31.001px"/><path d="M 30.905 18.817 L 27.318 12.544 L 26.897 11.805 L 28.795 8.485 C 28.86 8.371 28.893 8.243 28.893 8.117 C 28.893 7.991 28.86 7.861 28.795 7.749 L 26.685 4.058 C 26.619 3.944 26.528 3.853 26.419 3.789 C 26.309 3.725 26.183 3.69 26.054 3.69 L 18.035 3.69 L 16.135 0.368 C 16.004 0.141 15.764 0 15.502 0 L 11.282 0 C 11.151 0 11.026 0.035 10.917 0.099 C 10.808 0.163 10.714 0.256 10.648 0.368 L 7.062 6.644 L 6.64 7.38 L 2.842 7.38 C 2.711 7.38 2.586 7.416 2.477 7.48 C 2.368 7.543 2.274 7.636 2.208 7.749 L 0.098 11.434 C 0.033 11.549 0 11.677 0 11.803 C 0 11.928 0.033 12.059 0.098 12.171 L 4.109 19.183 L 2.208 22.505 C 2.143 22.619 2.11 22.747 2.11 22.873 C 2.11 22.999 2.143 23.129 2.208 23.241 L 4.318 26.931 C 4.384 27.046 4.478 27.137 4.585 27.201 C 4.694 27.265 4.821 27.3 4.95 27.3 L 12.968 27.3 L 14.868 30.622 C 14.999 30.849 15.239 30.99 15.502 30.99 L 19.722 30.99 C 19.853 30.99 19.977 30.955 20.086 30.891 C 20.196 30.827 20.29 30.734 20.353 30.622 L 24.363 23.61 L 28.162 23.61 C 28.293 23.61 28.417 23.575 28.526 23.511 C 28.636 23.447 28.729 23.354 28.793 23.241 L 30.903 19.551 C 30.968 19.437 31.001 19.309 31.001 19.183 C 31.001 19.057 30.968 18.927 30.903 18.815 Z M 11.282 0.732 L 13.392 4.425 L 11.282 8.115 L 28.164 8.115 L 26.054 11.805 L 9.593 11.805 L 7.271 7.744 Z M 12.97 26.57 L 4.952 26.57 L 7.062 22.875 L 11.282 22.875 L 2.842 8.113 L 7.062 8.113 L 9.172 11.803 L 15.29 22.507 L 12.97 26.568 Z M 26.051 19.185 L 23.942 15.495 L 15.502 30.258 L 13.392 26.568 L 15.504 22.877 L 21.624 12.175 L 26.268 12.175 L 30.276 19.185 L 26.054 19.185 Z" fill="url(%23SpY9X9apg-855988464-linear-gradient)" height="30.99px" id="SpY9X9apg" transform="translate(0 1)" width="31.001px"/><path d="M 30.905 18.817 L 27.318 12.544 L 26.897 11.805 L 28.795 8.485 C 28.86 8.371 28.893 8.243 28.893 8.117 C 28.893 7.991 28.86 7.861 28.795 7.749 L 26.685 4.058 C 26.619 3.944 26.528 3.853 26.419 3.789 C 26.309 3.725 26.183 3.69 26.054 3.69 L 18.035 3.69 L 16.135 0.368 C 16.004 0.141 15.764 0 15.502 0 L 11.282 0 C 11.151 0 11.026 0.035 10.917 0.099 C 10.808 0.163 10.714 0.256 10.648 0.368 L 7.062 6.644 L 6.64 7.38 L 2.842 7.38 C 2.711 7.38 2.586 7.416 2.477 7.48 C 2.368 7.543 2.274 7.636 2.208 7.749 L 0.098 11.434 C 0.033 11.549 0 11.677 0 11.803 C 0 11.928 0.033 12.059 0.098 12.171 L 4.109 19.183 L 2.208 22.505 C 2.143 22.619 2.11 22.747 2.11 22.873 C 2.11 22.999 2.143 23.129 2.208 23.241 L 4.318 26.931 C 4.384 27.046 4.478 27.137 4.585 27.201 C 4.694 27.265 4.821 27.3 4.95 27.3 L 12.968 27.3 L 14.868 30.622 C 14.999 30.849 15.239 30.99 15.502 30.99 L 19.722 30.99 C 19.853 30.99 19.977 30.955 20.086 30.891 C 20.196 30.827 20.29 30.734 20.353 30.622 L 24.363 23.61 L 28.162 23.61 C 28.293 23.61 28.417 23.575 28.526 23.511 C 28.636 23.447 28.729 23.354 28.793 23.241 L 30.903 19.551 C 30.968 19.437 31.001 19.309 31.001 19.183 C 31.001 19.057 30.968 18.927 30.903 18.815 Z M 11.282 0.732 L 13.392 4.425 L 11.282 8.115 L 28.164 8.115 L 26.054 11.805 L 9.593 11.805 L 7.271 7.744 Z M 12.97 26.57 L 4.952 26.57 L 7.062 22.875 L 11.282 22.875 L 2.842 8.113 L 7.062 8.113 L 9.172 11.803 L 15.29 22.507 L 12.97 26.568 Z M 26.051 19.185 L 23.942 15.495 L 15.502 30.258 L 13.392 26.568 L 15.504 22.877 L 21.624 12.175 L 26.268 12.175 L 30.276 19.185 L 26.054 19.185 Z" fill="url(%23NaGTTODDA-855988464-linear-gradient)" height="30.99px" id="NaGTTODDA" transform="translate(0 1)" width="31.001px"/></svg>)
Qwen3.6-27B
$0.32
$0.20 (Cached)
$3.20
Qwen3.8-27B
$0.40
$0.20 (Cached)
$3.00
" height="3.18602px" id="Mot1JnCWx" transform="translate(8.172 4.385)" width="3.186020000000001px"/><path d="M 1.593 3.186 C 2.473 3.186 3.186 2.473 3.186 1.593 C 3.186 0.713 2.473 0 1.593 0 C 0.713 0 0 0.713 0 1.593 C 0 2.473 0.713 3.186 1.593 3.186 Z" fill="rgb(234, 67, 53)" height="3.1860999999999997px" id="QzjbpJgO1" transform="translate(8.172 11.021)" width="3.186020000000001px"/><path d="M 1.593 3.186 C 2.473 3.186 3.186 2.473 3.186 1.593 C 3.186 0.713 2.473 0 1.593 0 C 0.713 0 0 0.713 0 1.593 C 0 2.473 0.713 3.186 1.593 3.186 Z" fill="rgb(234, 67, 53)" height="3.186px" id="VOhCVjNdL" transform="translate(8.172 17.66)" width="3.186020000000001px"/><path d="M 1.593 3.186 C 2.473 3.186 3.186 2.473 3.186 1.593 C 3.186 0.713 2.473 0 1.593 0 C 0.713 0 0 0.713 0 1.593 C 0 2.473 0.713 3.186 1.593 3.186 Z" fill="rgb(234, 67, 53)" height="3.186px" id="XMo00pRkF" transform="translate(8.172 24.297)" width="3.186020000000001px"/><path d="M 1.858 3.717 C 2.885 3.717 3.717 2.885 3.717 1.859 C 3.717 0.832 2.885 0 1.858 0 C 0.832 0 0 0.832 0 1.859 C 0 2.885 0.832 3.717 1.858 3.717 Z" fill="rgb(251, 188, 4)" height="3.717029px" id="qYFO1zen0" transform="translate(13.609 0.801)" width="3.7169999999999987px"/><path d="M 1.858 3.717 C 2.885 3.717 3.717 2.885 3.717 1.858 C 3.717 0.832 2.885 0 1.858 0 C 0.832 0 0 0.832 0 1.858 C 0 2.885 0.832 3.717 1.858 3.717 Z" fill="rgb(251, 188, 4)" height="3.7171000000000003px" id="fNtqXUNkT" transform="translate(13.609 7.438)" width="3.7169999999999987px"/><path d="M 1.858 3.717 C 2.885 3.717 3.717 2.885 3.717 1.859 C 3.717 0.832 2.885 0 1.858 0 C 0.832 0 0 0.832 0 1.859 C 0 2.885 0.832 3.717 1.858 3.717 Z" fill="rgb(251, 188, 4)" height="3.7170000000000005px" id="oVas2FOg2" transform="translate(13.609 14.074)" width="3.7169999999999987px"/><path d="M 1.858 3.717 C 2.885 3.717 3.717 2.885 3.717 1.859 C 3.717 0.832 2.885 0 1.858 0 C 0.832 0 0 0.832 0 1.859 C 0 2.885 0.832 3.717 1.858 3.717 Z" fill="rgb(251, 188, 4)" height="3.7169999999999987px" id="t9yPe33o5" transform="translate(13.609 20.713)" width="3.7169999999999987px"/><path d="M 1.858 3.717 C 2.885 3.717 3.717 2.885 3.717 1.859 C 3.717 0.832 2.885 0 1.858 0 C 0.832 0 0 0.832 0 1.859 C 0 2.885 0.832 3.717 1.858 3.717 Z" fill="rgb(251, 188, 4)" height="3.717100000000002px" id="tEXbsZpog" transform="translate(13.609 27.482)" width="3.7169999999999987px"/><path d="M 2.19 4.381 C 3.4 4.381 4.381 3.4 4.381 2.19 C 4.381 0.981 3.4 0 2.19 0 C 0.981 0 0 0.981 0 2.19 C 0 3.4 0.981 4.381 2.19 4.381 Z" fill="rgb(52, 168, 83)" height="4.380790000000001px" id="zpwkpUJ5i" transform="translate(18.922 3.854)" width="4.380800000000001px"/><path d="M 2.19 4.381 C 3.4 4.381 4.381 3.4 4.381 2.19 C 4.381 0.981 3.4 0 2.19 0 C 0.981 0 0 0.981 0 2.19 C 0 3.4 0.981 4.381 2.19 4.381 Z" fill="rgb(52, 168, 83)" height="4.380800000000001px" id="oTO6IE7YB" transform="translate(18.922 10.49)" width="4.380800000000001px"/><path d="M 2.19 4.381 C 3.4 4.381 4.381 3.4 4.381 2.19 C 4.381 0.981 3.4 0 2.19 0 C 0.981 0 0 0.981 0 2.19 C 0 3.4 0.981 4.381 2.19 4.381 Z" fill="rgb(52, 168, 83)" height="4.380799999999997px" id="LHaxikfTD" transform="translate(18.922 17.129)" width="4.380800000000001px"/><path d="M 2.19 4.381 C 3.4 4.381 4.381 3.4 4.381 2.19 C 4.381 0.981 3.4 0 2.19 0 C 0.981 0 0 0.981 0 2.19 C 0 3.4 0.981 4.381 2.19 4.381 Z" fill="rgb(52, 168, 83)" height="4.380800000000001px" id="i6z4mnKuF" transform="translate(18.922 23.766)" width="4.380800000000001px"/><path d="M 2.522 5.045 C 3.915 5.045 5.044 3.915 5.044 2.522 C 5.044 1.129 3.915 0 2.522 0 C 1.129 0 0 1.129 0 2.522 C 0 3.915 1.129 5.045 2.522 5.045 Z" fill="rgb(66, 133, 244)" height="5.04456px" id="u1D9Ur4zV" transform="translate(24.234 6.773)" width="5.044499999999999px"/><path d="M 1.328 2.655 C 2.061 2.655 2.655 2.061 2.655 1.327 C 2.655 0.594 2.061 0 1.328 0 C 0.594 0 0 0.594 0 1.327 C 0 2.061 0.594 2.655 1.328 2.655 Z" fill="rgb(66, 133, 244)" height="2.6550499999999992px" id="p99Z07P3p" transform="translate(2.727 7.969)" width="2.65503px"/><path d="M 1.328 2.655 C 2.061 2.655 2.655 2.061 2.655 1.328 C 2.655 0.594 2.061 0 1.328 0 C 0.594 0 0 0.594 0 1.328 C 0 2.061 0.594 2.655 1.328 2.655 Z" fill="rgb(66, 133, 244)" height="2.655000000000001px" id="w2UcRLJu8" transform="translate(2.727 14.605)" width="2.65503px"/><path d="M 1.328 2.655 C 2.061 2.655 2.655 2.061 2.655 1.328 C 2.655 0.594 2.061 0 1.328 0 C 0.594 0 0 0.594 0 1.328 C 0 2.061 0.594 2.655 1.328 2.655 Z" fill="rgb(66, 133, 244)" height="2.655100000000001px" id="DUZQppugi" transform="translate(2.727 21.244)" width="2.65503px"/><path d="M 2.522 5.045 C 3.915 5.045 5.044 3.915 5.044 2.522 C 5.044 1.129 3.915 0 2.522 0 C 1.129 0 0 1.129 0 2.522 C 0 3.915 1.129 5.045 2.522 5.045 Z" fill="rgb(66, 133, 244)" height="5.044500000000001px" id="IDQbKPhi3" transform="translate(24.234 13.412)" width="5.044499999999999px"/><path d="M 2.522 5.045 C 3.915 5.045 5.044 3.915 5.044 2.522 C 5.044 1.129 3.915 0 2.522 0 C 1.129 0 0 1.129 0 2.522 C 0 3.915 1.129 5.045 2.522 5.045 Z" fill="rgb(66, 133, 244)" height="5.044599999999999px" id="Y4VY9BvhU" transform="translate(24.234 20.049)" width="5.044499999999999px"/></g></svg>)
gemma-4-31B-it
$0.20
$0.05 (Cached)
$0.50
" width="27.201359884185788px"><path d="M 24.803 10.73 C 24.218 10.576 23.632 10.424 23.047 10.267 C 19.85 9.413 16.653 8.557 13.456 7.702 C 10.464 6.901 7.472 6.101 4.48 5.301 C 3.003 4.906 1.526 4.511 0.05 4.115 C 0.037 4.112 0.025 4.107 0 4.097 C 0.025 4.058 0.045 4.02 0.07 3.985 C 1.226 2.349 2.67 1.026 4.405 0.024 C 4.462 -0.009 4.557 -0.003 4.626 0.015 C 5.899 0.352 7.171 0.694 8.443 1.034 C 11.354 1.813 14.264 2.591 17.175 3.37 C 17.196 3.376 17.216 3.383 17.236 3.389 C 16.607 4.031 15.981 4.669 15.329 5.334 C 15.594 5.406 15.813 5.466 16.033 5.525 C 18.713 6.242 21.393 6.96 24.075 7.674 C 24.19 7.704 24.238 7.76 24.27 7.869 C 24.521 8.729 24.699 9.602 24.779 10.495 C 24.783 10.529 24.795 10.563 24.803 10.597 Z" fill="rgb(0, 0, 0)" height="10.729867025484081px" id="WLsTX0XbN" transform="translate(2.398 1.807)" width="24.802919999999997px"/><path d="M 0 0.409 C 0.014 0.279 0.028 0.149 0.044 0 C 4.33 1.147 8.609 2.292 12.885 3.435 C 12.707 4.197 12.532 4.948 12.354 5.714 C 16.456 6.812 20.534 7.903 24.629 8.999 C 24.555 9.098 24.491 9.187 24.424 9.274 C 23.884 9.973 23.286 10.616 22.622 11.2 C 22.569 11.246 22.526 11.27 22.448 11.249 C 18.688 10.24 14.928 9.234 11.167 8.228 C 7.949 7.367 4.731 6.505 1.512 5.644 C 1.29 5.585 1.067 5.53 0.847 5.462 C 0.796 5.445 0.733 5.393 0.716 5.343 C 0.319 4.181 0.088 2.987 0.023 1.761 C 0.02 1.708 0.008 1.657 0 1.605 C 0 1.206 0 0.808 0 0.409 Z" fill="rgb(0, 0, 0)" height="11.256879747836324px" id="dlb8PtZ3R" transform="translate(0 12.606)" width="24.62876px"/><path d="M 11.846 8.028 C 11.564 8.003 11.282 7.981 11.001 7.952 C 9.343 7.783 7.766 7.328 6.283 6.568 C 3.486 5.133 1.414 2.991 0.067 0.15 C 0.046 0.107 0.028 0.064 0 0 C 0.333 0.089 0.647 0.173 0.962 0.257 C 4.193 1.121 7.424 1.986 10.656 2.846 C 10.779 2.879 10.809 2.928 10.811 3.052 C 10.823 3.729 10.847 4.405 10.864 5.082 C 10.866 5.166 10.895 5.201 10.98 5.224 C 13.086 5.784 15.189 6.348 17.294 6.912 C 17.391 6.938 17.489 6.966 17.592 7.018 C 17.33 7.115 17.07 7.218 16.806 7.307 C 15.622 7.707 14.407 7.946 13.158 8.007 C 13.118 8.009 13.08 8.021 13.041 8.028 Z" fill="rgb(0, 0, 0)" height="8.028200000000005px" id="Oauh1HGal" transform="translate(1.195 19.172)" width="17.59185px"/><path d="M 6.053 0 C 6.224 0.016 6.394 0.034 6.565 0.048 C 8.529 0.208 10.372 0.77 12.09 1.732 C 13.746 2.658 15.145 3.882 16.295 5.392 C 16.311 5.413 16.327 5.434 16.342 5.456 C 16.347 5.463 16.349 5.472 16.362 5.502 C 10.911 4.044 5.475 2.59 0 1.126 C 0.174 1.054 0.314 0.993 0.456 0.937 C 1.692 0.458 2.968 0.151 4.291 0.049 C 4.463 0.036 4.633 0.016 4.804 0 C 5.221 0 5.637 0 6.053 0 Z" fill="rgb(0, 0, 0)" height="5.50216px" id="aQ4oTdCuN" transform="translate(8.187 0)" width="16.3617px"/><path d="M 26.912 9.152 C 26.75 10.079 26.501 10.965 26.155 11.832 C 17.44 9.501 8.733 7.171 0 4.835 C 0.092 4.395 0.171 3.961 0.275 3.533 C 0.568 2.327 1.028 1.187 1.639 0.107 C 1.693 0.012 1.737 -0.019 1.852 0.012 C 4.54 0.735 7.23 1.455 9.919 2.174 C 11.639 2.634 13.36 3.093 15.08 3.553 C 15.135 3.568 15.189 3.587 15.234 3.601 C 14.856 4.303 14.48 5.002 14.093 5.722 C 18.382 6.87 22.64 8.009 26.912 9.152 Z" fill="rgb(0, 0, 0)" height="11.83169523467746px" id="TFczAg3bx" transform="translate(0.125 6.787)" width="26.91206px"/></g></svg>)
Kimi K2.7 Code
$0.65
$0.20 (Cached)
$3.50
Kimi K3
$3.00
$0.50 (Cached)
$12.50
" height="28.821360000000002px" id="K0Xt7ivgd" transform="translate(1.586 1.59)" width="28.83196px"/><path d="M 10.421 0.011 L 9.035 1.984 C 8.821 2.293 8.459 2.485 8.075 2.485 L 0.501 2.485 L 0.501 0 C 0.491 0.011 10.421 0.011 10.421 0.011 Z M 19.84 0.011 L 7.936 16.875 L 0 16.875 L 11.904 0.011 Z M 9.419 16.875 L 10.816 14.891 C 11.029 14.581 11.392 14.389 11.776 14.389 L 19.339 14.389 L 19.339 16.875 Z" fill="rgb(255, 255, 255)" height="16.874700346374514px" id="XJq_orxHM" transform="translate(6.078 7.563)" width="19.839979999999997px"/></svg>)
GLM-5.2
$0.80
$0.20 (Cached)
$3.50
GLM-5.3 Flash
$0.15
$0.03 (Cached)
$0.50
GLM-5.3
$1.00
$0.30 (Cached)
$4.00
" height="22.40002965957478px" id="XZSyiY5gG" transform="translate(0.797 4.801)" width="30.400044773684026px"/></svg>)
DeepSeek V4 Flash
$0.15
$0.08 (Cached)
$0.25
DeepSeek V4.1 Flash
$0.30
$0.02 (Cached)
$0.60
DeepSeek V4 Pro
$1.00
$0.25 (Cached)
$2.50
" width="28.9999986134546px"><path d="M 1.037 0 L 9.19 0 C 9.469 0.225 10.048 0.213 10.414 0.58 C 11.164 1.332 11.598 2.259 12.246 3.09 C 12.48 3.391 12.68 3.72 12.894 4.035 L 17.786 11.144 C 17.964 11.403 18.189 11.664 18.355 11.921 C 18.865 12.718 19.406 13.492 19.969 14.252 C 20.079 14.402 20.208 14.684 20.319 14.808 C 20.659 15.186 20.918 15.784 21.251 16.132 C 21.196 15 21.219 13.718 21.219 12.574 L 21.217 3.309 C 21.217 2.705 21.199 2.039 21.247 1.444 C 21.296 0.857 21.843 0.374 22.347 0.148 C 22.429 0.109 22.568 0.053 22.634 0 L 28.716 0 C 28.746 1.703 28.736 3.442 28.722 5.147 C 28.687 9.257 28.769 13.383 28.726 17.49 C 27.512 17.393 25.673 17.445 24.418 17.445 L 16.825 17.445 L 14.47 17.45 C 14.051 17.452 13.61 17.464 13.194 17.44 C 13.058 17.425 12.934 17.36 12.844 17.257 C 12.674 17.061 12.57 16.703 12.419 16.514 C 12.062 16.067 11.758 15.585 11.435 15.114 L 9.101 11.69 C 8.644 11.018 8.236 10.489 7.812 9.778 C 7.777 10.182 7.834 10.93 7.836 11.378 L 7.832 15.126 C 7.832 15.77 7.865 16.871 7.804 17.486 C 7.334 17.433 6.846 17.444 6.372 17.444 L 4.522 17.444 C 3.092 17.444 1.415 17.402 0 17.447 L 0 10.516 C 0.363 9.872 0.399 9.948 0.829 9.464 C 1.816 9.198 6.257 9.305 7.476 9.349 C 7.368 9.13 7.172 8.923 7.031 8.72 C 6.885 8.51 6.741 8.298 6.597 8.086 L 2.532 2.16 C 2.073 1.494 1.583 0.83 1.107 0.174 C 1.066 0.125 1.042 0.064 1.037 0 Z" fill="rgb(97, 122, 214)" height="17.489999833198432px" id="qwEWVYKgK" width="28.73880740206976px"/><path d="M 11.345 0.014 C 12.639 -0.099 13.894 0.491 14.633 1.559 C 15.373 2.627 15.483 4.009 14.922 5.181 C 14.361 6.352 13.215 7.133 11.919 7.227 C 9.936 7.37 8.21 5.887 8.052 3.905 C 7.894 1.924 9.365 0.186 11.345 0.014 Z M 11.883 5.641 C 13.003 5.506 13.801 4.489 13.667 3.37 C 13.533 2.25 12.516 1.451 11.396 1.586 C 10.276 1.72 9.478 2.737 9.612 3.857 C 9.746 4.976 10.763 5.775 11.883 5.641 Z M 15.605 0.212 C 15.822 0.2 16.058 0.196 16.275 0.198 C 17.657 0.211 19.054 0.168 20.435 0.217 C 20.414 0.699 20.411 1.181 20.427 1.664 C 19.867 1.644 19.277 1.699 18.723 1.67 L 18.723 5.63 C 18.726 6.098 18.728 6.595 18.693 7.061 C 18.413 7.058 17.382 7.081 17.157 7.03 C 17.075 6.795 17.107 5.234 17.107 4.856 L 17.108 1.674 C 16.535 1.668 15.915 1.651 15.346 1.666 C 15.397 1.241 15.31 0.717 15.388 0.31 C 15.458 0.234 15.489 0.246 15.605 0.212 Z M 21.335 0.252 C 21.653 0.202 21.976 0.186 22.297 0.206 C 22.523 0.2 22.927 0.211 22.927 0.211 L 22.934 0.705 C 22.908 0.633 22.952 0.785 22.934 0.705 C 22.969 1.926 22.924 3.251 22.94 4.481 C 22.948 5.088 22.974 6.501 22.903 7.066 C 22.396 7.049 21.882 7.068 21.368 7.044 C 21.312 6.824 21.331 5.344 21.331 5.02 L 21.335 0.253 Z M 1.5 0.239 C 1.989 0.756 2.43 1.501 2.883 2.063 C 3.023 2.237 3.351 2.806 3.516 2.916 C 3.643 2.901 3.732 2.808 3.803 2.702 C 4.211 2.098 4.632 1.504 5.068 0.921 C 5.272 0.644 5.459 0.216 5.837 0.205 C 6.24 0.194 6.697 0.18 7.097 0.22 C 7.111 1.634 7.113 3.05 7.104 4.464 C 7.104 5.191 7.14 6.36 7.089 7.054 C 6.581 7.067 6 7.023 5.542 7.043 C 5.546 5.766 5.504 4.261 5.564 3.007 C 5.177 3.35 3.736 5.425 3.524 5.464 C 3.229 5.164 3.02 4.793 2.763 4.483 C 2.343 3.976 1.994 3.498 1.606 2.973 C 1.522 3.861 1.616 5.027 1.582 5.936 C 1.569 6.275 1.608 6.726 1.55 7.055 C 1.174 7.06 0.36 7.083 0 7.03 L 0 0.257 C 0.368 0.181 1.125 0.173 1.5 0.239 Z M 24.297 0.229 C 24.783 0.174 25.614 0.196 26.12 0.196 C 27.08 0.191 28.04 0.196 29 0.21 L 29 1.656 C 28.264 1.676 27.527 1.652 26.791 1.664 C 26.486 1.669 26.182 1.679 25.877 1.672 L 25.878 3.034 C 26.781 3.054 27.685 3.041 28.59 3.059 C 28.621 3.491 28.607 4.094 28.587 4.527 C 27.709 4.479 26.73 4.555 25.879 4.508 C 25.869 5.35 25.901 6.231 25.844 7.065 C 25.569 7.055 24.487 7.025 24.275 7.076 C 24.243 5.072 24.293 3.058 24.267 1.052 C 24.264 0.787 24.267 0.492 24.297 0.229 Z" fill="rgb(0, 0, 0)" height="7.236191856389849px" id="YzFZe8B_B" transform="translate(0 20.5)" width="28.9999986134546px"/></g></svg>)
Motif 3
$0.50
$0.20 (Cached)
$2.00
" height="30.399981890534598px" id="XoC7rqF_A" transform="translate(0.797 0.801)" width="30.399988365291172px"/></g></svg>)
gpt-oss-120b
$0.15
$0.08 (Cached)
$0.60
Features
Production ready
from day one.
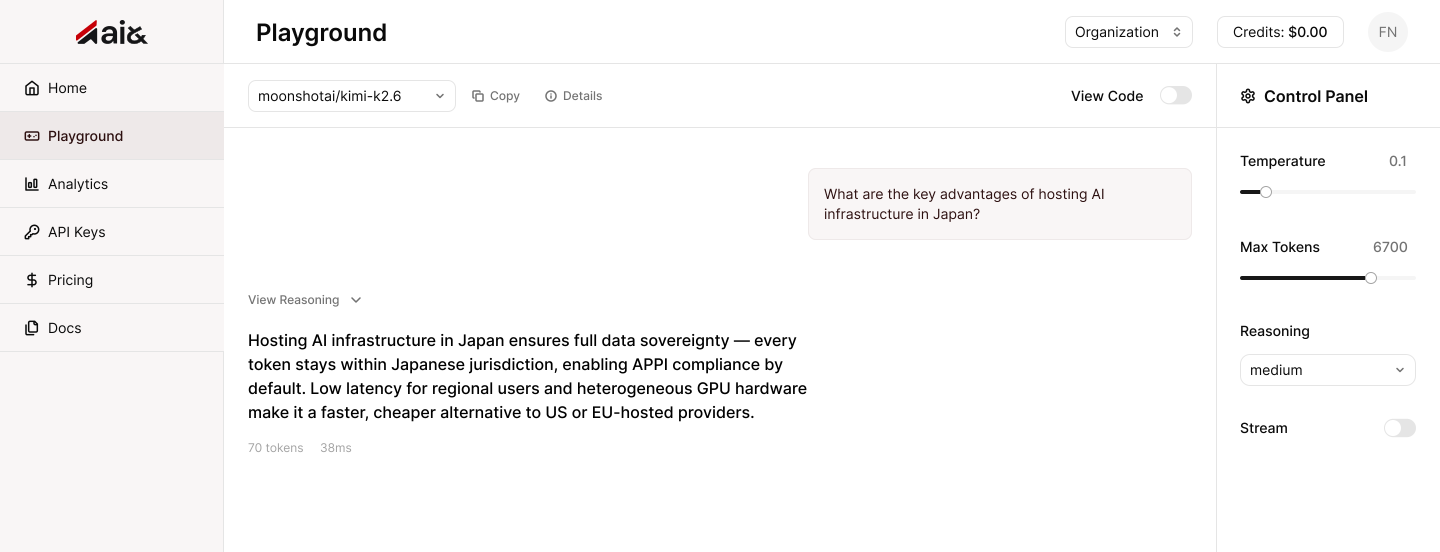
Every request processed in Japan, on infrastructure that scales automatically with your usage and easily drops into your existing OpenAI and Anthropic compatible tools.
Hosted In Japan
All inference runs on ai&'s Japan-based infrastructure purpose-built for the lowest possible latency across Asia-Pacific and beyond.
Data Resident
Your data stays in Japan. We never use your inputs or outputs for model training, and we comply fully with Japanese data residency requirements.
Scales With You
From zero to at scale concurrent requests in seconds. No cold starts, no capacity planning, just elasticity that matches your traffic.
OpenAI Compatible
A true drop-in replacement. Switch to ai& by changing one line of code, streaming, tool calling, and structured outputs all work out of the box.